A8079 | Genetic engineering
时间限制1s
内存限制256MB
通过 / 提交0/0
题目描述
"Multidimensional spaces are completely out of style these days, unlike genetics problems" — thought physicist Woll and changed his subject of study to bioinformatics. Analysing results of sequencing he faced the following problem concerning DNA sequences. We will further think of a DNA sequence as an arbitrary string of uppercase letters "A", "C", "G" and "T" (of course, this is a simplified interpretation).
Let $w$ be a long DNA sequence and $s_{1},s_{2},...,s_{m}$ — collection of short DNA sequences. Let us say that the collection filters $w$ iff $w$ can be covered with the sequences from the collection. Certainly, substrings corresponding to the different positions of the string may intersect or even cover each other. More formally: denote by $|w|$ the length of $w$ , let symbols of $w$ be numbered from $1$ to $|w|$ . Then for each position $i$ in $w$ there exist pair of indices $l,r$ ( $1<=l<=i<=r<=|w|$ ) such that the substring $w[l ... r]$ equals one of the elements $s_{1},s_{2},...,s_{m}$ of the collection.
Woll wants to calculate the number of DNA sequences of a given length filtered by a given collection, but he doesn't know how to deal with it. Help him! Your task is to find the number of different DNA sequences of length $n$ filtered by the collection ${s_{i}}$ .
Answer may appear very large, so output it modulo $1000000009$ .
输入格式
First line contains two integer numbers $n$ and $m$ ( $1<=n<=1000,1<=m<=10$ ) — the length of the string and the number of sequences in the collection correspondently.
Next $m$ lines contain the collection sequences $s_{i}$ , one per line. Each $s_{i}$ is a nonempty string of length not greater than $10$ . All the strings consist of uppercase letters "A", "C", "G", "T". The collection may contain identical strings.
Next $m$ lines contain the collection sequences $s_{i}$ , one per line. Each $s_{i}$ is a nonempty string of length not greater than $10$ . All the strings consist of uppercase letters "A", "C", "G", "T". The collection may contain identical strings.
输出格式
Output should contain a single integer — the number of strings filtered by the collection modulo $1000000009$ ( $10^{9}+9$ ).
输入输出样例
输入 #1
2 1
A
输出 #1
1
输入 #2
6 2
CAT
TACT
输出 #2
2
In the first sample, a string has to be filtered by "A". Clearly, there is only one such string: "AA".
In the second sample, there exist exactly two different strings satisfying the condition (see the pictures below).
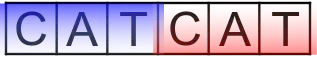 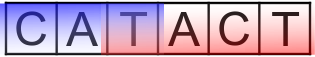
In the second sample, there exist exactly two different strings satisfying the condition (see the pictures below).
 
C++ 编辑器
输入
输出
可保存默认模板;新题优先使用已保存模板。
当前快捷键仅展示,暂不支持修改。
- 撤销
Ctrl / ⌘ + Z - 重做
Ctrl / ⌘ + Y - 查找
Ctrl / ⌘ + F - 全选
Ctrl / ⌘ + A - 复制
Ctrl / ⌘ + C - 剪切
Ctrl / ⌘ + X - 粘贴
Ctrl / ⌘ + V - 自动排版
工具栏排版按钮 - 草稿保存
编辑时自动保存到本机
历史
提交记录
状态说明时间源码
AI
作答助手
你好,我是作答助手。可以问思路、复杂度、样例含义或代码报错原因;不会直接给出完整 AC 代码。
确定要清空代码吗?
提交通过
评测结果:Accepted