A14517 | Chainword
时间限制1s
内存限制256MB
通过 / 提交0/0
题目描述
A chainword is a special type of crossword. As most of the crosswords do, it has cells that you put the letters in and some sort of hints to what these letters should be.
The letter cells in a chainword are put in a single row. We will consider chainwords of length $m$ in this task.
A hint to a chainword is a sequence of segments such that the segments don't intersect with each other and cover all $m$ letter cells. Each segment contains a description of the word in the corresponding cells.
The twist is that there are actually two hints: one sequence is the row above the letter cells and the other sequence is the row below the letter cells. When the sequences are different, they provide a way to resolve the ambiguity in the answers.
You are provided with a dictionary of $n$ words, each word consists of lowercase Latin letters. All words are pairwise distinct.
An instance of a chainword is the following triple:
- a string of $m$ lowercase Latin letters;
- the first hint: a sequence of segments such that the letters that correspond to each segment spell a word from the dictionary;
- the second hint: another sequence of segments such that the letters that correspond to each segment spell a word from the dictionary.
Note that the sequences of segments don't necessarily have to be distinct.
Two instances of chainwords are considered different if they have different strings, different first hints or different second hints.
Count the number of different instances of chainwords. Since the number might be pretty large, output it modulo $998\,244\,353$ .
The letter cells in a chainword are put in a single row. We will consider chainwords of length $m$ in this task.
A hint to a chainword is a sequence of segments such that the segments don't intersect with each other and cover all $m$ letter cells. Each segment contains a description of the word in the corresponding cells.
The twist is that there are actually two hints: one sequence is the row above the letter cells and the other sequence is the row below the letter cells. When the sequences are different, they provide a way to resolve the ambiguity in the answers.
You are provided with a dictionary of $n$ words, each word consists of lowercase Latin letters. All words are pairwise distinct.
An instance of a chainword is the following triple:
- a string of $m$ lowercase Latin letters;
- the first hint: a sequence of segments such that the letters that correspond to each segment spell a word from the dictionary;
- the second hint: another sequence of segments such that the letters that correspond to each segment spell a word from the dictionary.
Note that the sequences of segments don't necessarily have to be distinct.
Two instances of chainwords are considered different if they have different strings, different first hints or different second hints.
Count the number of different instances of chainwords. Since the number might be pretty large, output it modulo $998\,244\,353$ .
输入格式
The first line contains two integers $n$ and $m$ ( $1 \le n \le 8$ , $1 \le m \le 10^9$ ) — the number of words in the dictionary and the number of letter cells.
Each of the next $n$ lines contains a word — a non-empty string of no more than $5$ lowercase Latin letters. All words are pairwise distinct.
Each of the next $n$ lines contains a word — a non-empty string of no more than $5$ lowercase Latin letters. All words are pairwise distinct.
输出格式
Print a single integer — the number of different instances of chainwords of length $m$ for the given dictionary modulo $998\,244\,353$ .
输入输出样例
输入 #1
3 5
ababa
ab
a
输出 #1
11
输入 #2
2 4
ab
cd
输出 #2
4
输入 #3
5 100
a
aa
aaa
aaaa
aaaaa
输出 #3
142528942
Here are all the instances of the valid chainwords for the first example:
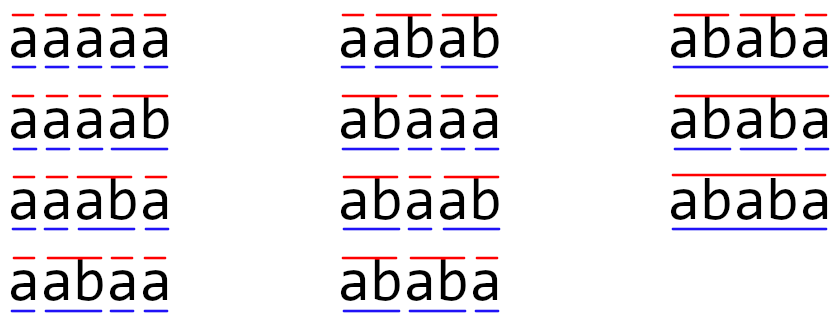The red lines above the letters denote the segments of the first hint, the blue lines below the letters denote the segments of the second hint.
In the second example the possible strings are: "abab", "abcd", "cdab" and "cdcd". All the hints are segments that cover the first two letters and the last two letters.
The red lines above the letters denote the segments of the first hint, the blue lines below the letters denote the segments of the second hint.
In the second example the possible strings are: "abab", "abcd", "cdab" and "cdcd". All the hints are segments that cover the first two letters and the last two letters.
C++ 编辑器
输入
输出
可保存默认模板;新题优先使用已保存模板。
当前快捷键仅展示,暂不支持修改。
- 撤销
Ctrl / ⌘ + Z - 重做
Ctrl / ⌘ + Y - 查找
Ctrl / ⌘ + F - 全选
Ctrl / ⌘ + A - 复制
Ctrl / ⌘ + C - 剪切
Ctrl / ⌘ + X - 粘贴
Ctrl / ⌘ + V - 自动排版
工具栏排版按钮 - 草稿保存
编辑时自动保存到本机
历史
提交记录
状态说明时间源码
AI
作答助手
你好,我是作答助手。可以问思路、复杂度、样例含义或代码报错原因;不会直接给出完整 AC 代码。
确定要清空代码吗?
提交通过
评测结果:Accepted