A11617 | Fafa and Ancient Alphabet
时间限制1s
内存限制256MB
通过 / 提交0/0
题目描述
Ancient Egyptians are known to have used a large set of symbols  to write on the walls of the temples. Fafa and Fifa went to one of the temples and found two non-empty words $S_{1}$ and $S_{2}$ of equal lengths on the wall of temple written one below the other. Since this temple is very ancient, some symbols from the words were erased. The symbols in the set  have equal probability for being in the position of any erased symbol.
Fifa challenged Fafa to calculate the probability that $S_{1}$ is lexicographically greater than $S_{2}$ . Can you help Fafa with this task?
You know that , i. e. there were $m$ distinct characters in Egyptians' alphabet, in this problem these characters are denoted by integers from $1$ to $m$ in alphabet order. A word $x$ is lexicographically greater than a word $y$ of the same length, if the words are same up to some position, and then the word $x$ has a larger character, than the word $y$ .
We can prove that the probability equals to some fraction , where $P$ and $Q$ are coprime integers, and 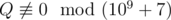. Print as the answer the value 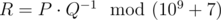, i. e. such a non-negative integer less than $10^{9}+7$ , such that 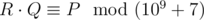, where 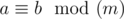 means that $a$ and $b$ give the same remainders when divided by $m$ .
Fifa challenged Fafa to calculate the probability that $S_{1}$ is lexicographically greater than $S_{2}$ . Can you help Fafa with this task?
You know that , i. e. there were $m$ distinct characters in Egyptians' alphabet, in this problem these characters are denoted by integers from $1$ to $m$ in alphabet order. A word $x$ is lexicographically greater than a word $y$ of the same length, if the words are same up to some position, and then the word $x$ has a larger character, than the word $y$ .
We can prove that the probability equals to some fraction , where $P$ and $Q$ are coprime integers, and 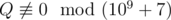. Print as the answer the value 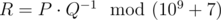, i. e. such a non-negative integer less than $10^{9}+7$ , such that 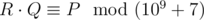, where 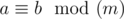 means that $a$ and $b$ give the same remainders when divided by $m$ .
输入格式
The first line contains two integers $n$ and $m$ ( $1<=n,m<=10^{5}$ ) — the length of each of the two words and the size of the alphabet , respectively.
The second line contains $n$ integers $a_{1},a_{2},...,a_{n}$ ( $0<=a_{i}<=m$ ) — the symbols of $S_{1}$ . If $a_{i}=0$ , then the symbol at position $i$ was erased.
The third line contains $n$ integers representing $S_{2}$ with the same format as $S_{1}$ .
The second line contains $n$ integers $a_{1},a_{2},...,a_{n}$ ( $0<=a_{i}<=m$ ) — the symbols of $S_{1}$ . If $a_{i}=0$ , then the symbol at position $i$ was erased.
The third line contains $n$ integers representing $S_{2}$ with the same format as $S_{1}$ .
输出格式
Print the value 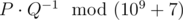, where $P$ and $Q$ are coprime and  is the answer to the problem.
输入输出样例
输入 #1
1 2
0
1
输出 #1
500000004
输入 #2
1 2
1
0
输出 #2
0
输入 #3
7 26
0 15 12 9 13 0 14
11 1 0 13 15 12 0
输出 #3
230769233
In the first sample, the first word can be converted into ( $1$ ) or ( $2$ ). The second option is the only one that will make it lexicographically larger than the second word. So, the answer to the problem will be 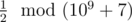, that is $500000004$ , because 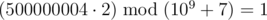.
In the second example, there is no replacement for the zero in the second word that will make the first one lexicographically larger. So, the answer to the problem is 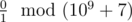, that is $0$ .
In the second example, there is no replacement for the zero in the second word that will make the first one lexicographically larger. So, the answer to the problem is 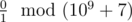, that is $0$ .
C++ 编辑器
输入
输出
可保存默认模板;新题优先使用已保存模板。
当前快捷键仅展示,暂不支持修改。
- 撤销
Ctrl / ⌘ + Z - 重做
Ctrl / ⌘ + Y - 查找
Ctrl / ⌘ + F - 全选
Ctrl / ⌘ + A - 复制
Ctrl / ⌘ + C - 剪切
Ctrl / ⌘ + X - 粘贴
Ctrl / ⌘ + V - 自动排版
工具栏排版按钮 - 草稿保存
编辑时自动保存到本机
历史
提交记录
状态说明时间源码
AI
作答助手
你好,我是作答助手。可以问思路、复杂度、样例含义或代码报错原因;不会直接给出完整 AC 代码。
确定要清空代码吗?
提交通过
评测结果:Accepted